
Artificial Intelligence Teaching Lab
Session 3: Grading Student Work in the Age of AI
Building on the assessment redesign conversation explored in the previous AI Teaching Lab session with Dr. Farah Nadeem and Dr. Irfan Muzaffar, the LUMS Learning Institute (LLI) continued the series with a session 3 focusing on a question that is becoming increasingly importatnt for educators:
Grading student work in the age of AI
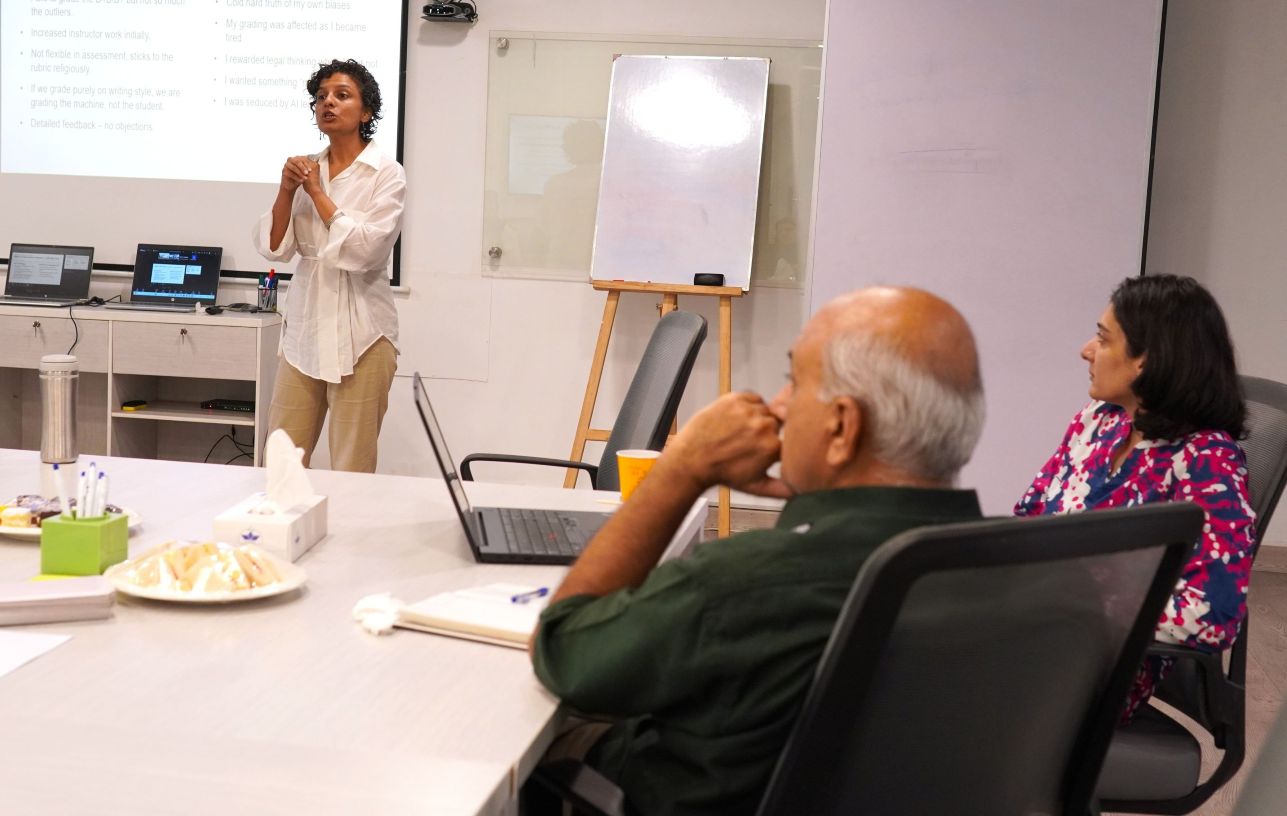
Led by Dr. Summaiya Zaidi from the Shaikh Ahmad Hassan School of Law (SAHSOL), Session 3 brought faculty together to think more carefully about grading, assessment, academic integrity, authorship, and the role of instructor judgment when AI is increasingly capable of producing polished academic work.
Rather than treating AI as simply a tool that can make grading faster, the discussion explored the complexities that arise when AI-supported evaluation meets instructor judgment. Faculty considered the role of rubrics, disciplinary thinking, writing quality, academic integrity, and context in determining what makes student work meaningful.
The session was also grounded in experience. Dr. Summaiya shared her own experiences of using AI, while participants reflected on and shared their experiences of working with AI in their own teaching and assessment contexts.
Case Studies: Divergences Between Instructor and the Rubric
A central part of the session was a case study based on a Right to Information request related to the Gul Plaza fire.
Participants examined student submissions alongside rubric-based AI evaluations and compared them with instructor assessments. The exercise revealed that the two approaches could align in some cases, while diverging considerably in others.
These differences became an important starting point for discussion.
The AI-supported rubric was able to assess many submissions consistently, particularly those that fell within the expected range. However, it was less effective with outlier responses and could become inflexible when applied too rigidly.
At the same time, instructor assessment was not necessarily free from limitations.
The discussion surfaced some difficult but useful reflections about grading. Instructor assessment could be affected by fatigue, expectations, writing style, and the desire to reward particular kinds of thinking. As Dr. Summaiya reflected through the exercise, there were moments when she rewarded legal thinking that the AI did not recognize, while at other times she found herself influenced by polished AI-generated legal prose.
The comparison therefore raised a broader question:
If we grade purely on writing style, are we grading the machine rather than the student?
The case study demonstrated that neither the rubric nor the instructor is automatically objective. Both can produce useful insights, but both also require critical examination.
What the Case Studies Revealed
The comparison between instructor and rubric-based assessments generated several important findings.
AI Can Handle the Expected — But Not Always the Outliers
AI-supported grading was able to work reasonably well for submissions that fell within an expected range. However, it struggled more with unusual or outlier responses.
This highlighted the importance of looking beyond whether an answer simply matches the criteria and considering what the student is actually demonstrating through their work.
Rubrics Can Support Consistency — But Can Also Become Rigid
A well-designed rubric can make expectations clearer and support consistency in grading. However, when applied too rigidly, it may fail to recognize disciplinary thinking, persuasive reasoning, or context that does not fit neatly within predefined criteria.
The session therefore encouraged faculty to think carefully about what their rubrics value and what they might leave out.
Instructor Judgment Is Not Perfect Either
The discussion was not about positioning human grading as automatically better than AI.
Instead, participants were encouraged to recognize their own biases and limitations. Grading can be affected by tiredness, expectations, writing style, and even the persuasiveness of a well-written response.
This made the comparison between AI and instructor assessment particularly valuable: it provided an opportunity to identify not only AI's errors, but also our own.
Detailed Feedback Is Valuable
The case study also highlighted the usefulness of detailed feedback generated through the assessment process. While AI-supported systems can provide structured and detailed feedback, faculty still need to determine whether that feedback is appropriate, relevant, and meaningful for the specific assignment and discipline.
Learning from Experience
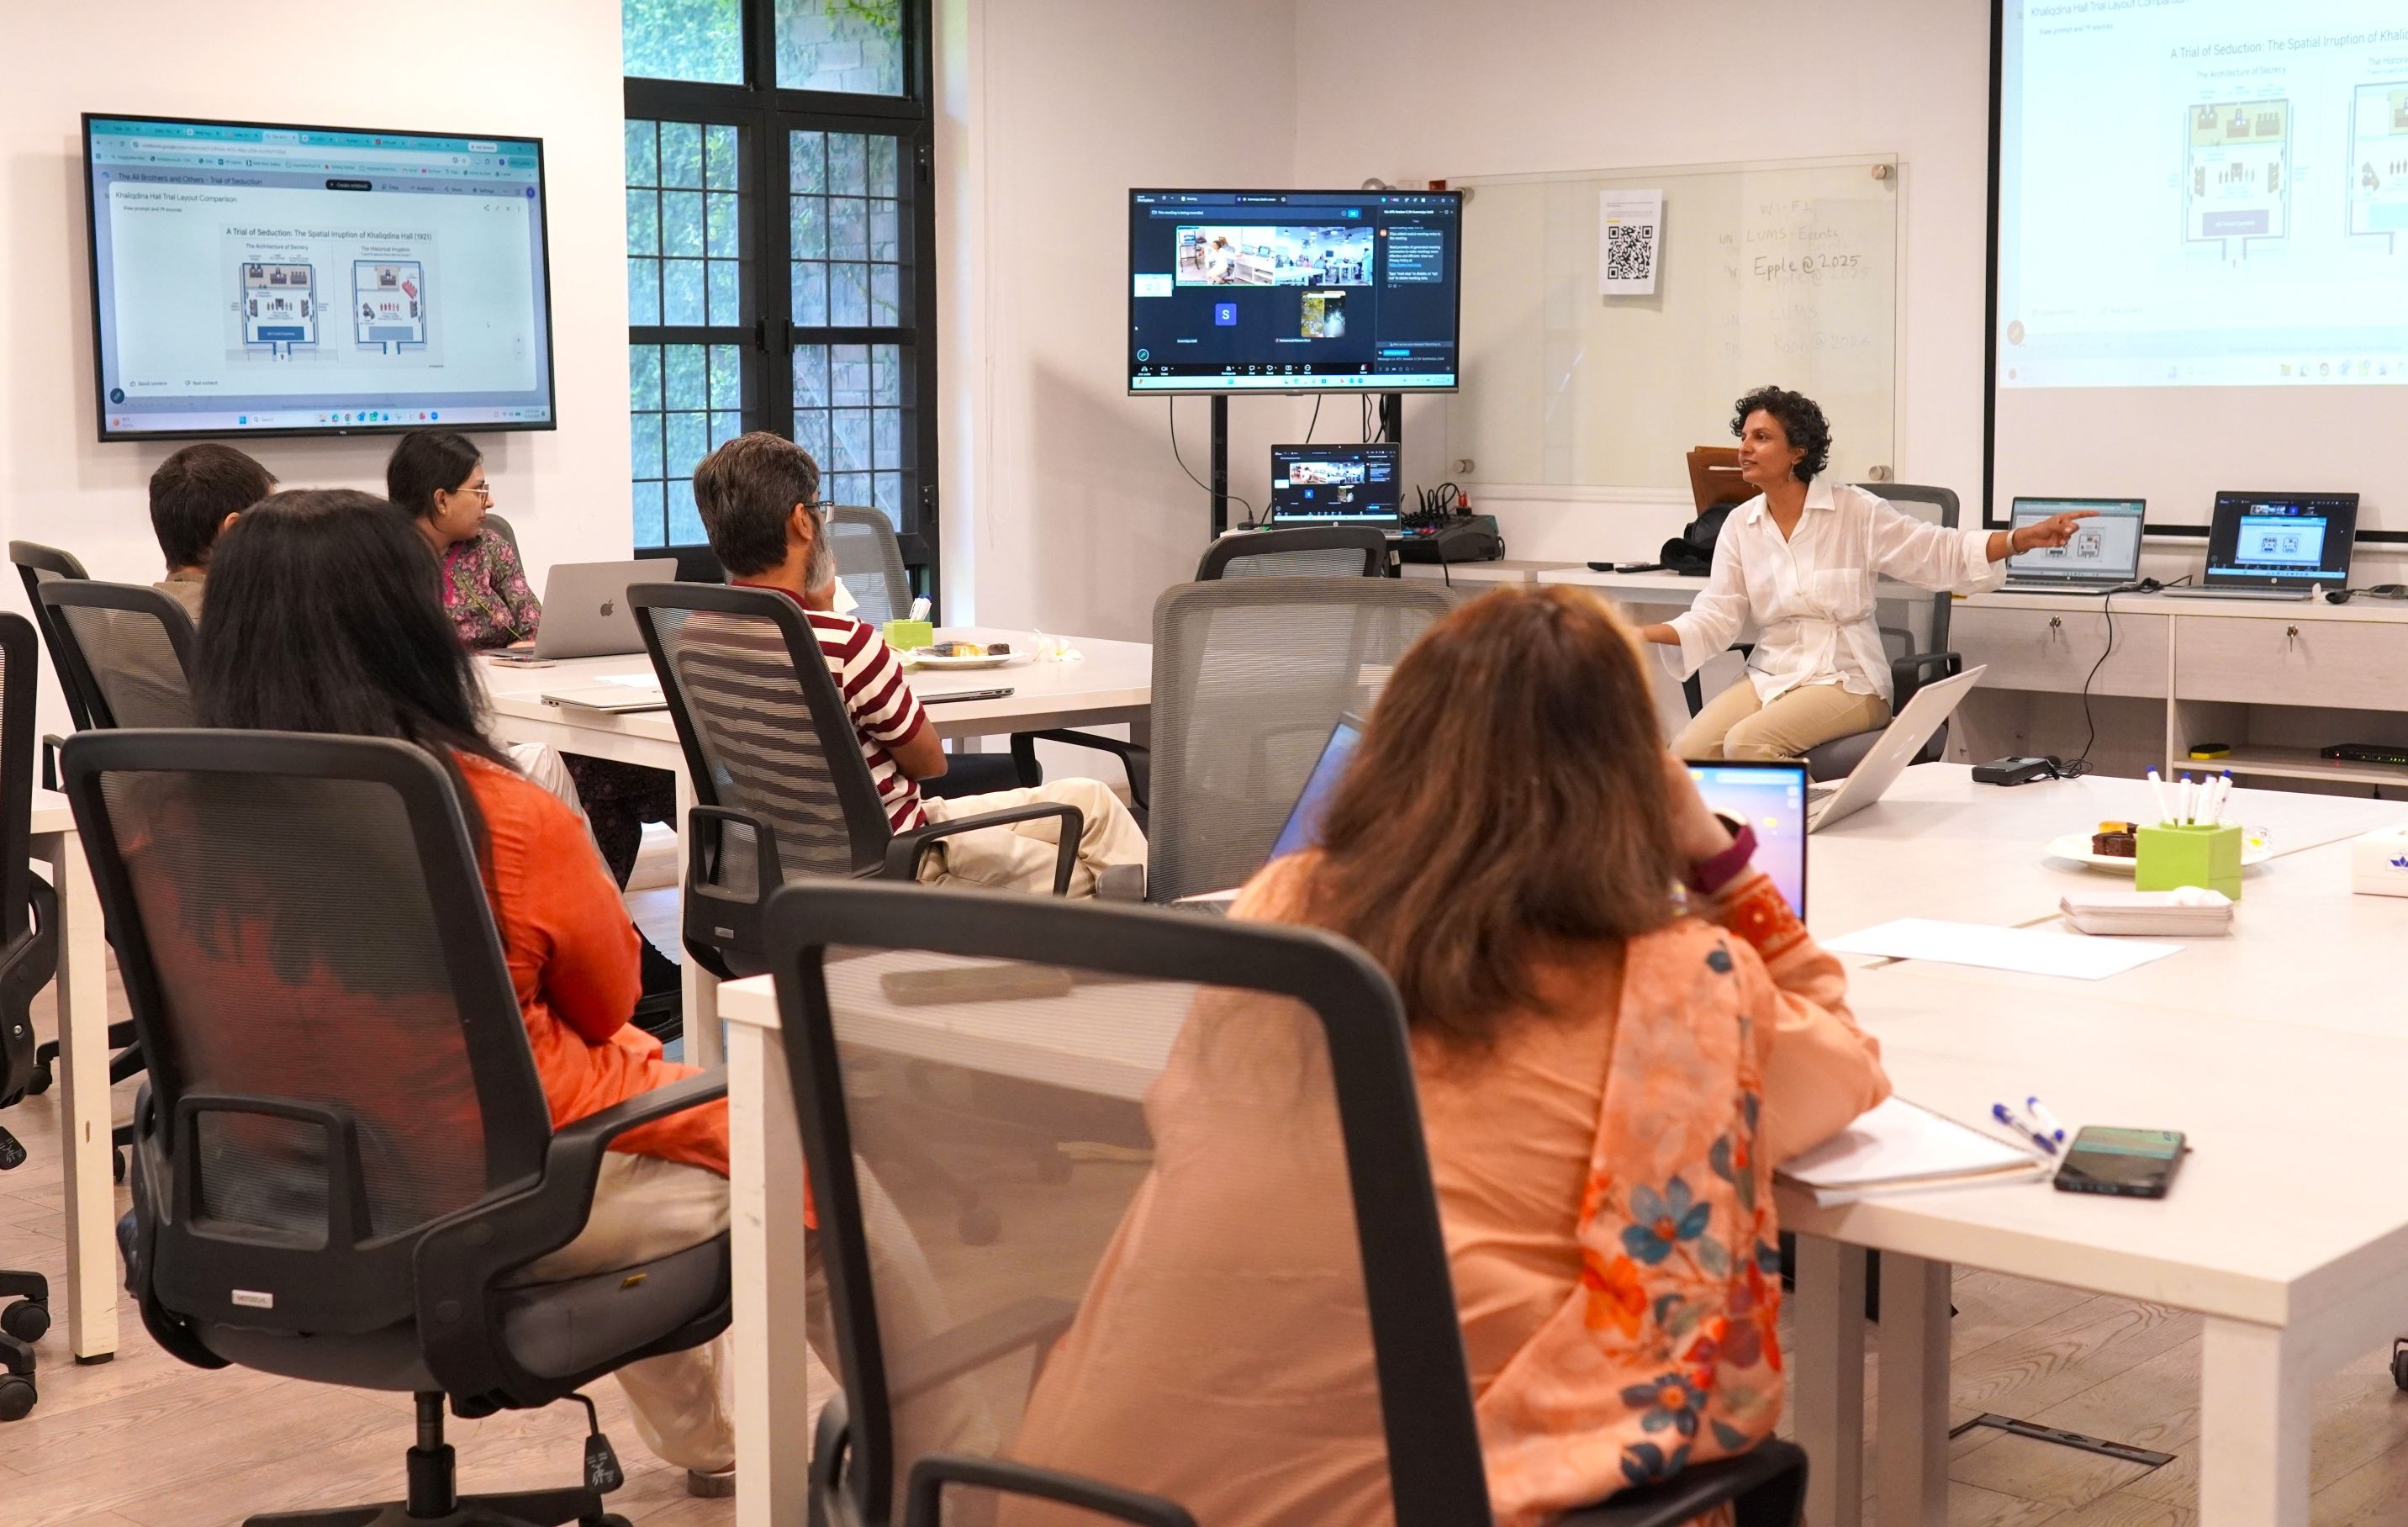
The session also created space for faculty to move beyond hypothetical discussions and share their own experiences.
Dr. Summaiya shared her experience of using AI herself, bringing a practical perspective to the conversation. Rather than approaching AI simply as something students use, the discussion considered how educators can also engage with these technologies thoughtfully in their own academic practice.
Participants similarly shared their experiences, questions, and concerns around AI and assessment.
These exchanges helped shift the conversation from “Should we use AI?” to a more practical discussion about where AI can support teaching and assessment, where it may fall short, and what should remain the responsibility of the instructor.
The value of the discussion came from this exchange of experiences. Faculty were able to consider not only what AI can do, but also how its use changes their own roles, expectations, and approaches to assessment.
Putting AI to the Test
The session then moved from case-study discussion to hands-on practice.
Faculty were invited to bring their own graded assessments, rubrics, and model answers and explore how AI could support their grading process. Using NotebookLM, participants experimented with generating and refining rubrics based on their own assessment needs.
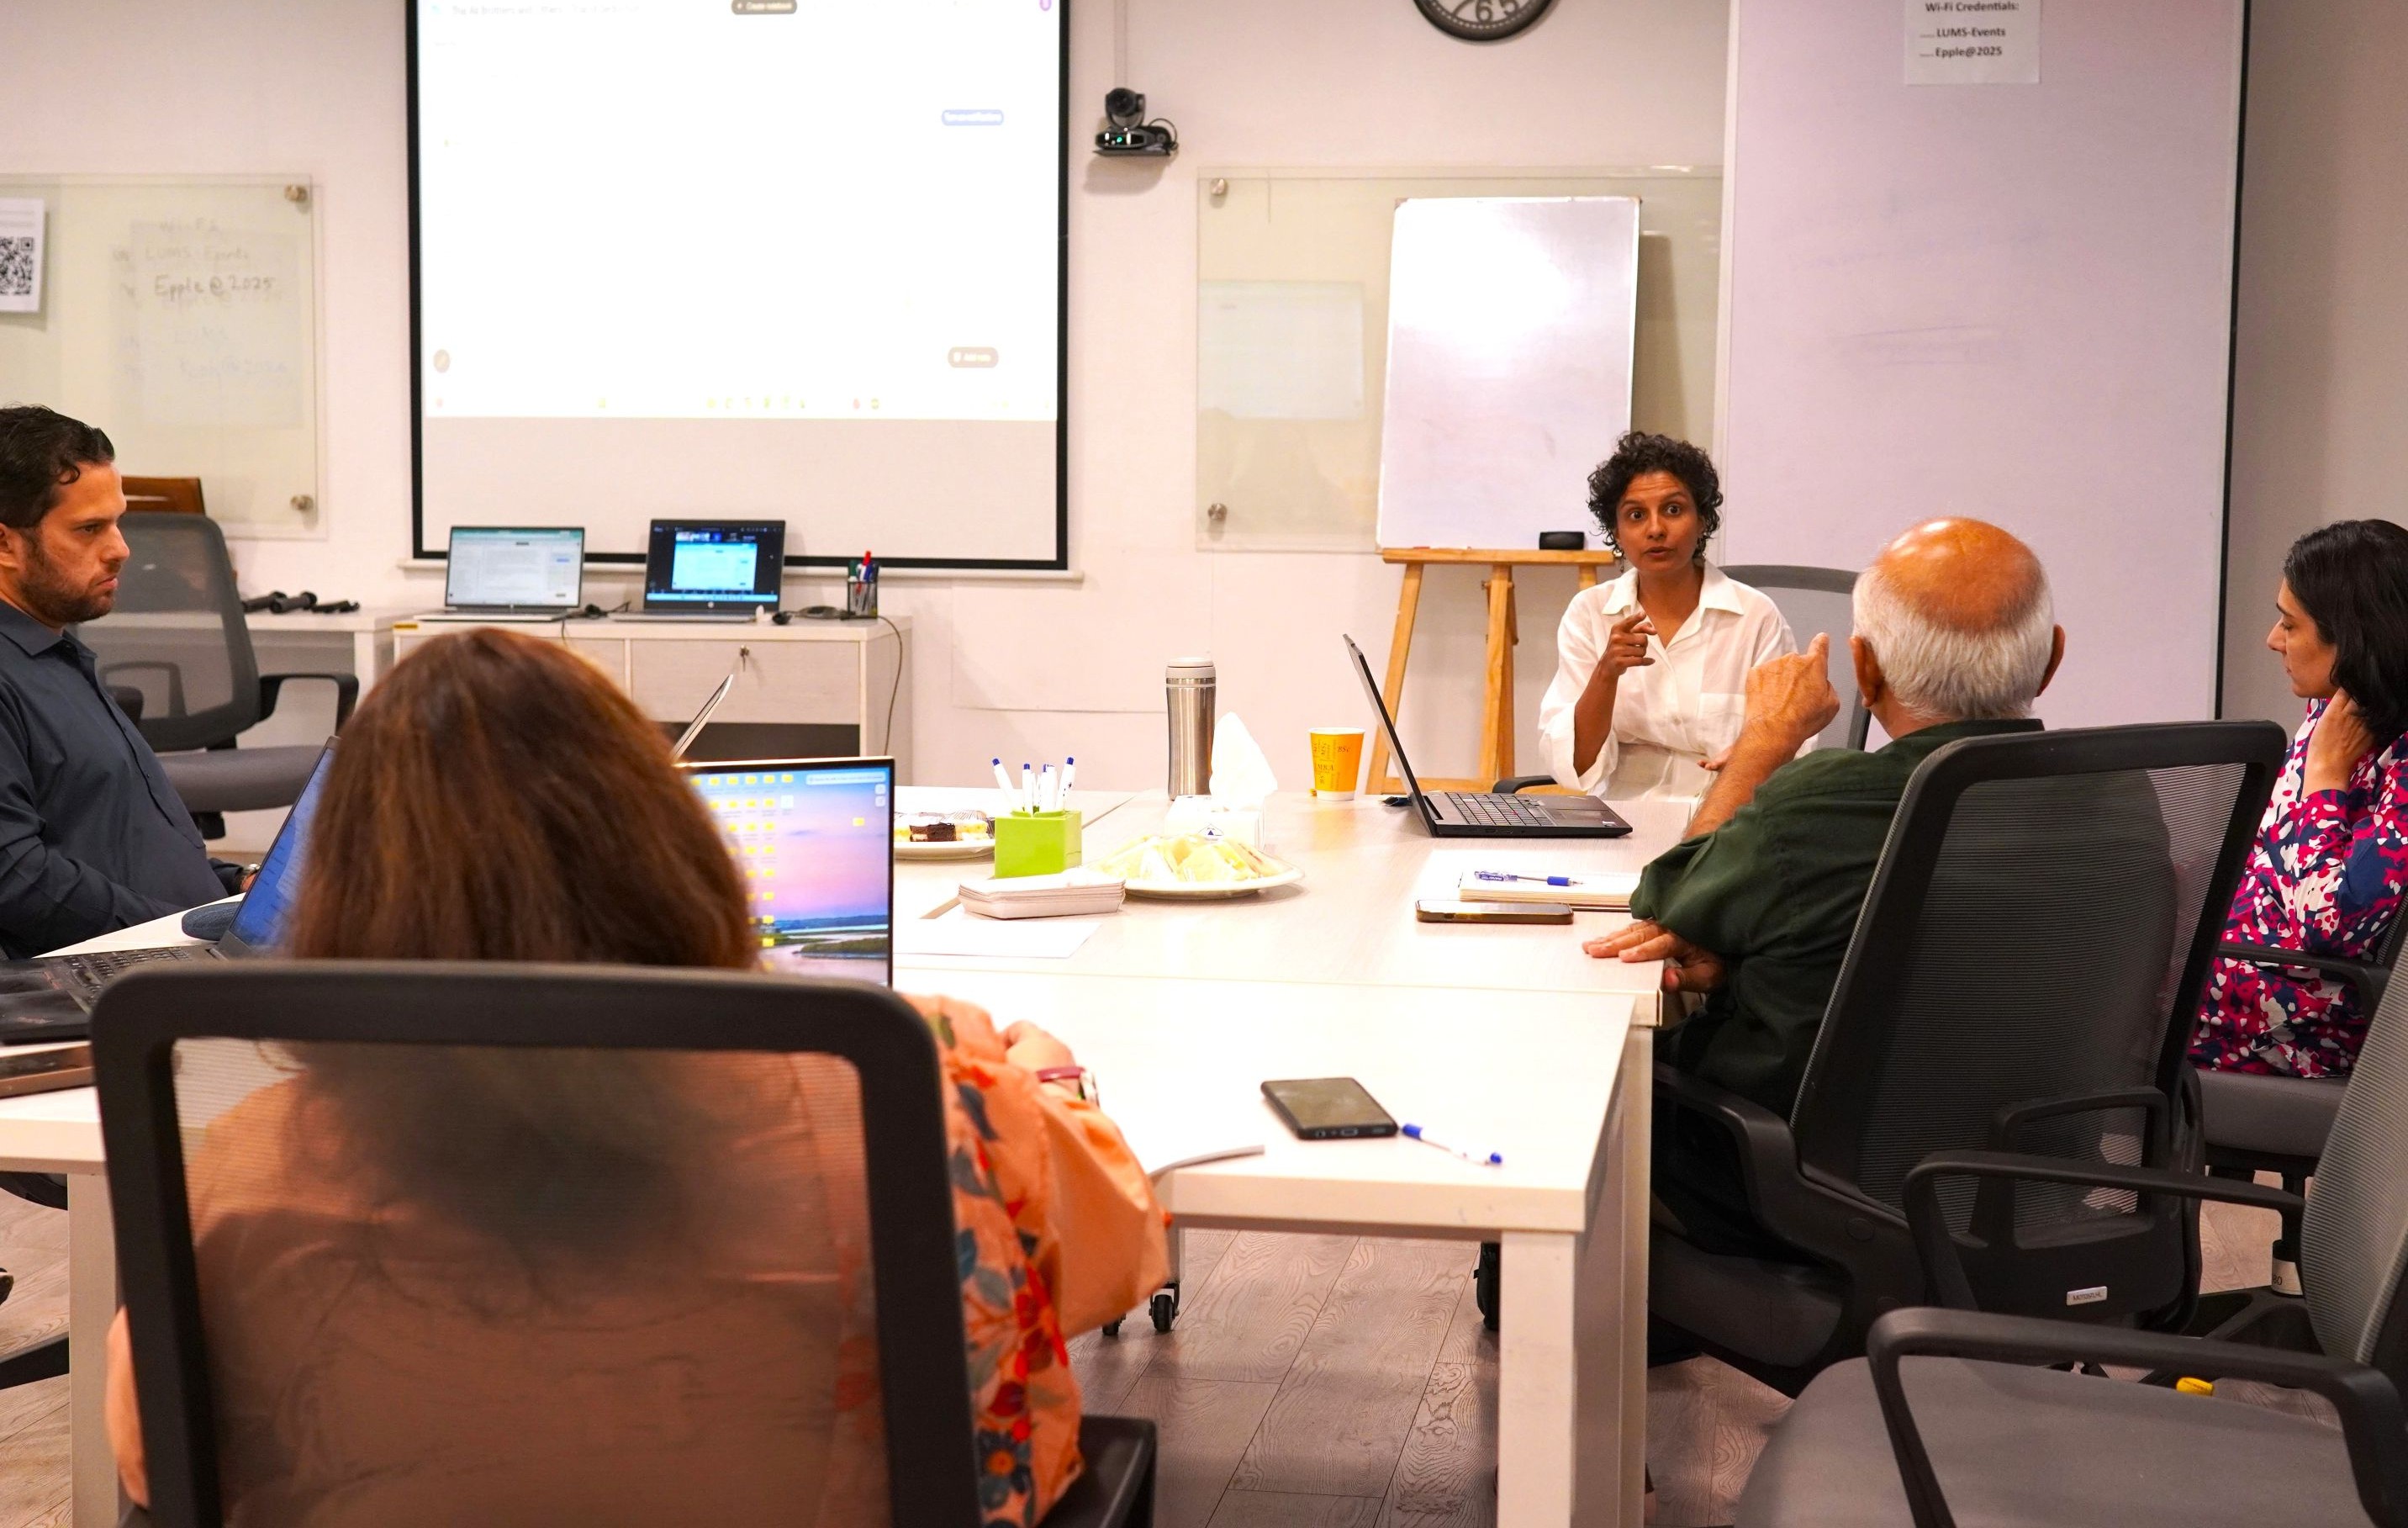
They were encouraged to test these rubrics against different levels of student work — including strong, weak, and mid-range submissions — and examine where the AI-supported evaluation worked and where it required adjustment.
This practical exercise reinforced that AI-supported grading cannot simply be adopted without testing.
It needs to be tested, refined, and reviewed.
It also provided faculty with an opportunity to examine their own grading practices alongside AI-generated evaluations and identify areas where either approach might need reconsideration.
Key Takeaways
The discussion concluded with several important reflections for faculty considering AI-supported assessment.
AI can work for some kinds of assignments, but not necessarily for others.
There should be no blind trust in AI-supported grading.
Assessment systems need to be developed around the needs of the instructor, discipline, and learning context.
Human judgment remains important, particularly when evaluating disciplinary thinking, context, and unexpected responses.
The session also emphasized that foundational errors should not be overlooked simply because an answer is well written. Beautiful writing should not rescue a structurally weak or logically incorrect response.
Ultimately, the goal is not to replace instructor judgment with AI, but to understand how the two can be brought into a more thoughtful relationship.
A Space for Rethinking Assessment
Session 3 of the AI Teaching Lab demonstrated that the conversation around AI and assessment is not simply about whether machines can grade.
It is also about what we value when we grade, what our rubrics recognize, what our judgments overlook, and what we consider evidence of student learning.
By examining real case studies, sharing experiences, testing AI-supported rubrics, and reflecting on their own assessment practices, faculty were able to engage with these questions critically and practically.
As AI continues to shape academic work, educators will need assessment approaches that are clear enough to provide consistency, flexible enough to recognize meaningful thinking, and thoughtful enough to keep human judgment at the center.
The AI Teaching Lab continues to provide a space for faculty to explore these questions together, learn from one another, and rethink teaching and assessment in an evolving AI-enabled educational landscape.
The goal is not blind adoption or complete rejection of AI. It is to understand where AI can support assessment — and where the educator's expertise, judgment, and responsibility must remain central.
AI Teaching Lab Series
The AI Teaching Lab is an ongoing faculty development initiative designed to foster thoughtful engagement with AI in teaching and learning.
➡️ Read the Session 1 Highlights
➡️ Read the Session 2 Highlights
➡️ Join the Next AI Teaching Lab Session. Register here.
Connect


